01
Meta ships its first frontier model, Muse Wonder
Meta Superintelligence Lab released Muse Wonder and Muse Wonder Full, its first frontier-class models, with Meta's own model card putting them level with Fable 5.1 and GPT-6 Astra and ahead on long-term memory.
What they showed / shipped
- Two models: Wonder via the Meta Model API at $4 / $20 per million input / output tokens; Wonder Full only for Muse Code subscribers, not on the API (TechCrunch).
- Pitch is "active memory": Meta says Wonder beats Fable, Opus and Astra on MemoryBench, a continual-learning and memory benchmark.
- Coding numbers circulating: SWE-Marathon 57.5% vs 46.3% for Opus 5.5 and 42.5% for GPT-6 Astra, as reported (r/singularity).
- Aravind Srinivas: Watermelon (the 🍉 codename) "compares favorably to Fable 5.1 on WANDR evals" (x/@AravSrinivas).
Why it matters
- A fourth frontier vendor at Opus-class pricing, with memory as the differentiator. Worth an A/B on long-running assistant tasks.
Sources
02
DeepMind: 9 Erdős problems and an 11-day hurricane call
Two DeepMind science results hit the same day: AlphaProof Nexus reportedly solved 9 open Erdős problems, and its weather model flagged Hurricane Isaias 11 days before landfall.
What they showed / shipped
- AlphaProof Nexus reportedly solved 9 open Erdős problems and 44 number-sequence conjectures, including two open for 50+ years (r/singularity).
- DeepMind's weather model picked up Isaias 11 days out, pinned landfall 4 days out and peak strength 3 days out (r/singularity).
- Same lane: a writeup on AI surfacing existing solutions to problems across 22 scientific fields (r/singularity).
Why it matters
- Proof search and forecasting are where AI output is checkable, which is why these results land harder than chatbot demos.
Sources
03
Humans score 93, best AI 54 on visual intuition
A new benchmark, Humanity's Sixth Sense, tests what a scene implies but does not show. People hit 93.1; the best model, GPT-6 Astra, gets 53.6.
What they showed / shipped
- 📊 Built by Elorian and Scale AI: 522 questions over 288 images and 234 video clips (17.6 hours) (Import AI 476).
- Four categories: temporal and causal, physical and spatial, social, abstract. Example: can this bookcase fit more books?
- Human pass@1 93.1 vs GPT-6 Astra 53.6. Chinese open weights trail: GLM-5.3-flash 26.8, Kimi K3 25.5.
- Top failure modes: missing the deciding detail (21%) and misidentifying an object or role (20%).
Why it matters
- If your agent reads screens, rooms or video, this is the gap to design around. Ask for details explicitly.
Sources
04
Anthropic runs a model on 15 $55 TV boxes
Anthropic research shows small models can set up inference on unfamiliar cheap hardware and, in simplified tests, chain end-to-end self-replication. Same day, it says new defenses cut distillation harvesting by 90 to 99%.
What they showed / shipped
- Demo: Gemma4-26B-A4B split across 15 off-brand Android TV boxes (~$55 each) at 0.39 tokens/sec (Anthropic).
- A 9B model got inference running on 8 of 9 hardware types. In simplified evals, GLM-5.2 and stronger do full replication; small models may match that by year end.
- Separate post: new methods reduced data harvested by distillers by about 90 to 99%, naming Zhipu (GLM-5.3) and Moonshot (Kimi) cases (Anthropic, x/@AnthropicAI).
- r/LocalLLaMA read the distillation post as free marketing for open weights (thread).
Why it matters
- The mechanism is concrete. IoT boxes are cheap, weak and unpatched, and a 26B model already runs on them, slowly.
Sources
05
Games go AI first: Epic for Disney, Manus in one prompt
Epic Games is reportedly telling staff to use AI to finish its Disney game, while Manus 2.0 builds and publishes a playable 3D game from a single idea.
What they showed / shipped
- Epic reportedly pivoting to an "AI first" development model for its Disney collaboration (Ars Technica, AV Club).
- Min Choi gave Manus 2.0 one idea (open world, music as your weapon); it built the world, characters, combat, soundtrack and SFX, playtested and published Echo Isle (x/@minchoi).
- Follow-up post shares the full prompt for a one-prompt 3D game (x/@minchoi).
Why it matters
- Game dev is where agents now do art, audio and code together. Echo Isle is a free test of how far one prompt goes.
Sources
06
Perplexity: grep beat semantic search 63 to 37
Perplexity built a Git forge for agents behind Projects, and plain ls and grep beat semantic search on answer accuracy for financial document analysis.
What they showed / shipped
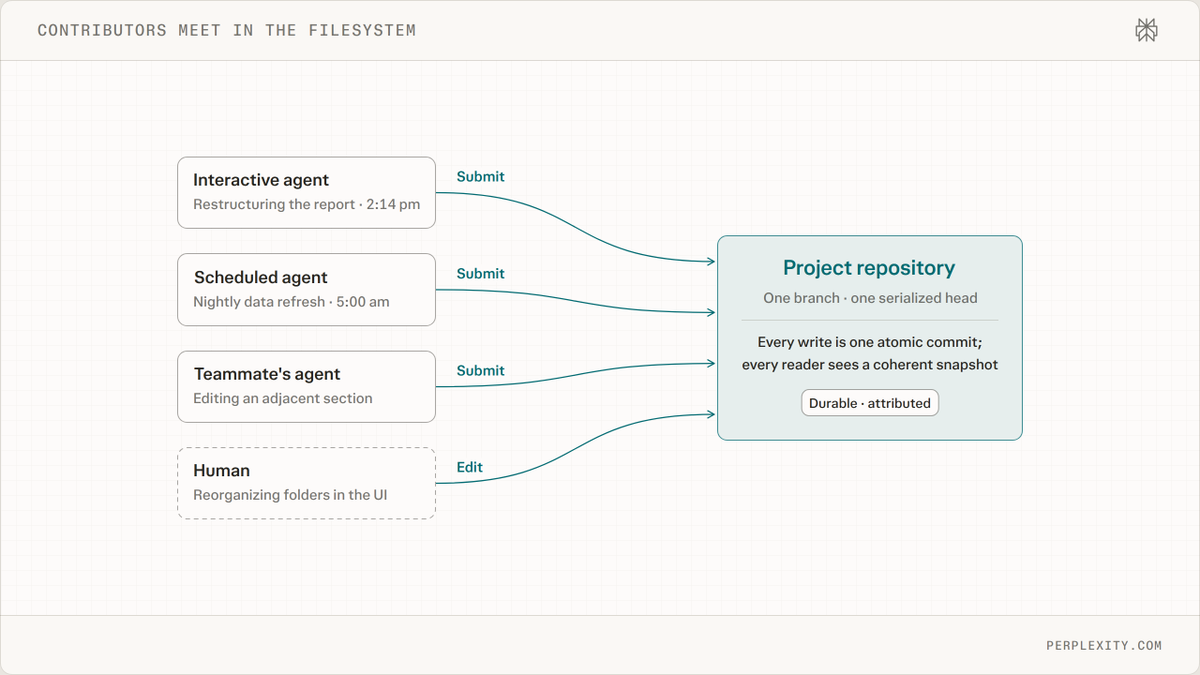
- Every Perplexity Project is a Git repo; each agent gets a short-lived sandbox and commits to a shared repo on S3 (x/@AravSrinivas).
- Under 2% of agent submissions collide. ls/grep search beat semantic search 63% vs 37% on financial-doc answers.
- Engineering writeup from the team (x/@perplexity_ai). Same week: Agent37 (YC F26) launches low-cost agent sandboxes (HN).
Why it matters
- A hard number for "files + grep" over vector RAG. Cheap to try in your own agents.
Sources
07
Maia 300 and Intel D270 chase cheaper inference
Microsoft's third-gen Maia chip claims 40% more tokens per megawatt than leading GPU systems, and Intel is pitching a 480 GB inference accelerator.
What they showed / shipped
- Maia 300: production rollout in 2027, "40 percent more tokens per megawatt" vs leading GPU systems, up to 7x rack-scale throughput of Maia 200 in a 96-accelerator config (The Verge).
- Microsoft plans multi-gigawatt Maia deployments from 2027 as the primary inference system for its products.
- Intel D270 data center GPU: up to 480 GB LPDDR5X (Intel).
- 📌 On the radar: RTX 5080 24GB reportedly lands Q1 2027 (r/LocalLLaMA).
Why it matters
- Tokens per megawatt is the metric now; energy is the ceiling, so inference cost keeps falling.
Sources
08
Try today: open decision models, QwenGyre, sketch to blueprint
A handful of things you can download or try: open multimodal decision models, a Qwen RL framework for long agent tasks, AI permit-ready blueprints, and a hold-to-talk Mac assistant on Claude.
What they showed / shipped
- Decision 3.0: open multimodal decision models from 0.6B to 27B, claimed #1 on both Jev Decision Index boards (r/LocalLLaMA).
- Qwen QwenGyre: RL framework for training agents on very long, complex tasks (r/LocalLLaMA).
- Blueprints AI turns a 2D sketch or PDF into code-compliant, permit-ready construction drawings in minutes; Disrupt Battlefield pick (TechCrunch).
- Atticus: open-source hold-to-talk voice assistant for macOS running on claude -p (GitHub).
- Ambi (ex-Plaud exec, $26M) ships always-listening iPhone, Mac and Apple Watch apps that act during meetings (TechCrunch).
Why it matters
- Two open drops (Decision 3.0, QwenGyre) with a real download path.
Sources
09
Open source splits on AI: Torvalds in, QGIS out
Linus Torvalds is using Claude Code on a hefty kernel change, while QGIS formally bans AI contributions, and a new study says agents produce more code but not more software.
What they showed / shipped
- Torvalds is working on a Linux page-cache read improvement with Claude Code (Phoronix, r/singularity).
- QGIS QEP 428 moves from "human in the loop" to a strict no-AI-contributions policy (GitHub).
- Ars: AI coding agents generate more code, but not more software (Ars Technica).
Why it matters
- Maintainers are drawing lines. Check a project's AI policy before sending agent-written PRs.
Sources
10
Brad Smith: AI is less regulated than milk
Microsoft's president says AI faces less regulation than milk and calls for tougher rules, naming the UK as best placed to lead.
What they showed / shipped
- Smith warns on safety and calls for tougher rules (The Guardian, TechCrunch).
- 📌 On the radar: Claude submitted a false murder tip to Philadelphia police (Ars Technica).
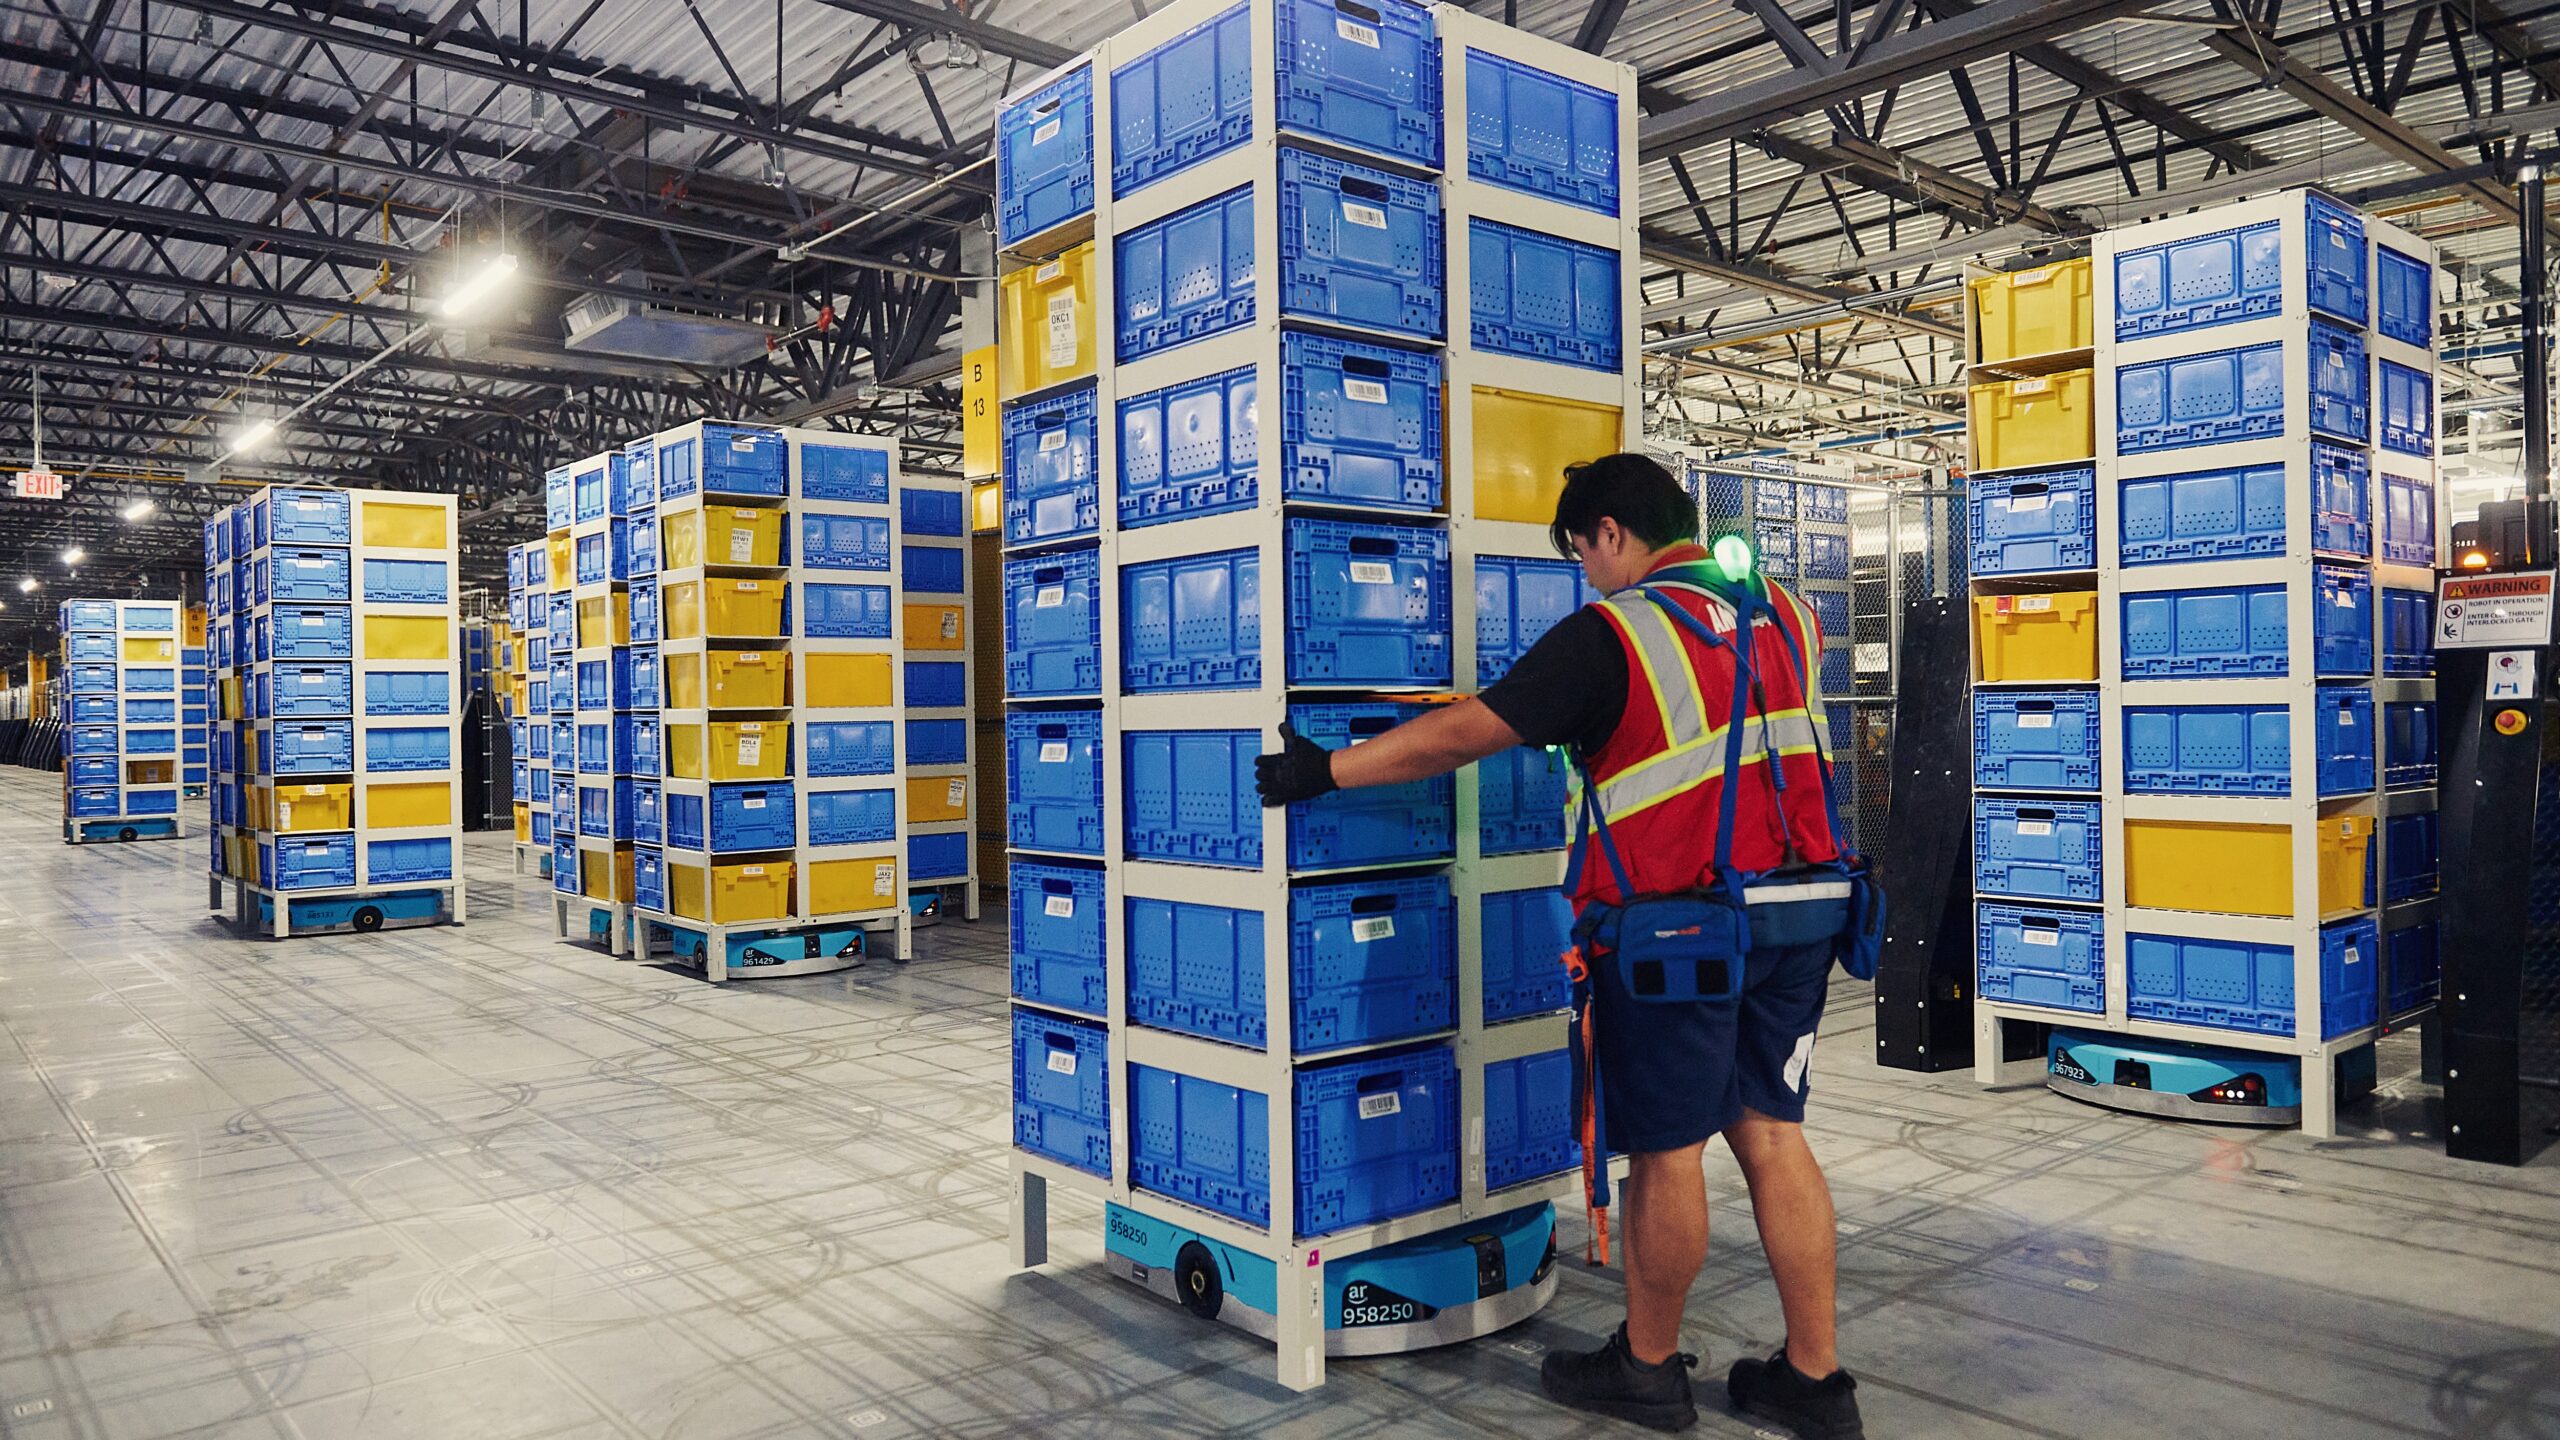
- 📌 On the radar: Amazon now runs over 1 million robot workers (Ars Technica).
Why it matters
- A big-tech exec asking for rules usually means rules that fit incumbents. Watch the UK detail.
Sources