01
AI video in under 10 seconds
A new fal x Black Forest Labs video model makes text-to-video clips in under 10 seconds, 22x faster than Seedance 2.5, and 3D world gen and Runway-in-chat landed the same day.
What they showed / shipped
- fal x BFL video model: every clip in the demo reel is text-to-video, generated in under 10 seconds, which venturetwins says is 22x faster than Seedance 2.5.
- Viggle unveiled JST-2: it builds whole 3D worlds in seconds, expands them in real time and animates characters, with physics built in instead of rendering flat video (r/singularity).
- Runway's MCP is now live inside Grok Bot, so Runway generation runs straight from a chat (x/@runwayml).
Why it matters
- Sub-10-second video turns gen into something you can loop on like an image model. Iteration speed is the real unlock, not one perfect clip.
Sources
02
Mercury 3 shows diffusion LLMs can scale
Inception's Mercury 3 writes text by diffusion instead of word by word, runs 1,000+ tokens a second and matches GPT-6 Luna and Claude Haiku 5.5 on their benchmarks.
What they showed / shipped
- Inception says Mercury 3 beats GPT-6 Luna and Claude Haiku 5.5 on a range of benchmarks while running 4 to 8x faster at 1,000+ tokens per second (inceptionlabs.ai).
- It is 40x larger than Mercury 1, and benchmark intelligence rose 3x. Their claim: the scaling laws behind normal LLMs hold for diffusion too.
- Price is $0.20 in and $0.70 out per million tokens, half off at launch. Early users run voice support, live tutoring and browser agents on it.
Why it matters
- Agents wait on the model at every step. A 4 to 8x faster model makes multi-step agents feel instant and lets them try more paths.
Sources
03
Try today: a 4B model with the AI tics trained out
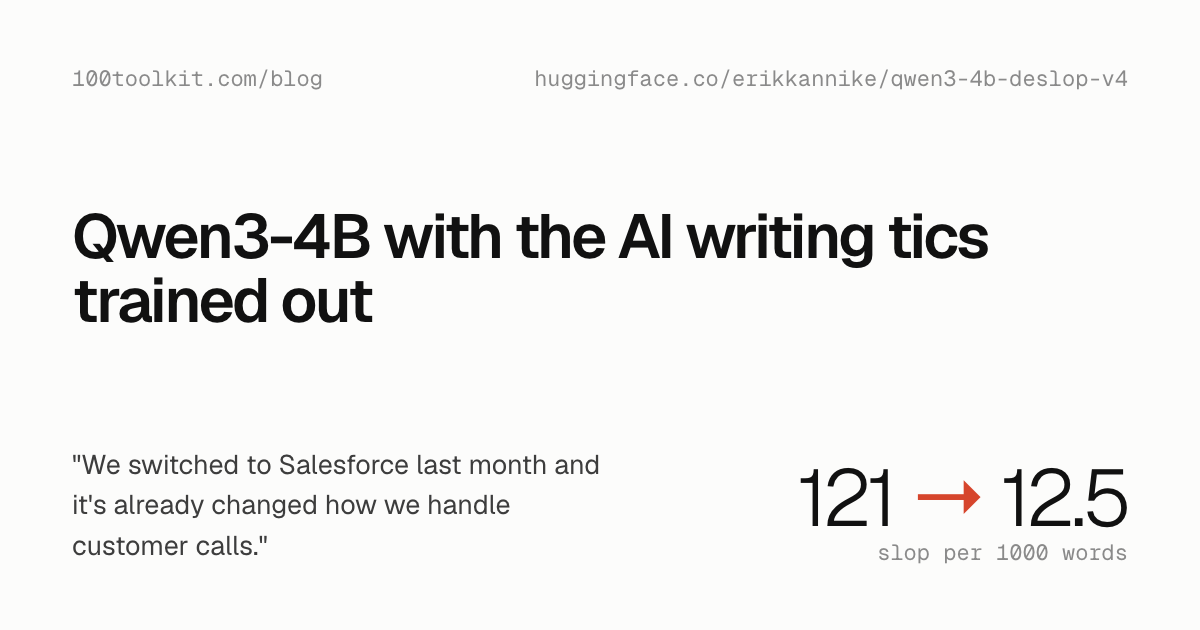
Someone trained the em dashes, 'it's not X, it's Y' and 'delve' out of Qwen3-4B on a MacBook Air, and it is a 2.5 GB Ollama download.
What they showed / shipped
- qwen3-4b-deslop: slop score fell from 121 to 12.5 per 1,000 words on 40 unseen prompts; 68% of answers land in the human range; em dashes went from 20.5 per 1,000 words to zero (100toolkit.com).
- Still 30 of 30 on factual questions. Trained on just 161 answers. Honest caveats: the voice is flat and it still invents names and places.
- Also new on r/LocalLLaMA: inclusionAI's Ming-3.0-audio-flash on Hugging Face, MiniMax M3.1 Flash is out with weights promised Oct 23, and llama.cpp now runs Cohere models.
Why it matters
- Proof that small targeted fine-tunes fix style problems prompts cannot. The recipe is model-size agnostic.
Sources
04
Mistral goes science: forecasting and collider physics
Mistral shipped Timestral, a 209M forecasting model that tops all three main time-series benchmarks on a CPU, and signed with CERN to build the first foundation model for collider physics.
What they showed / shipped
- Timestral comes in four sizes, 5M to 209M parameters. The largest ranks first on GIFT-Eval, TIME and fev-bench with two-thirds the parameters of the previous best, and runs on CPUs (mistral.ai).
- It forecasts many series at once with uncertainty ranges, and handles known future inputs like a production schedule. Uses: sensor drift, capacity planning, energy, finance.
- CERN and Mistral plan a single Large Physics Model trained on billions of simulated LHC collisions, to reconstruct events, identify particles and flag unexpected signals (home.cern).
- 📌 On the radar: Quanta asks what OpenAI's quasi-Riemann proof means for math (quantamagazine.org), and Fields Medalist Richard Borcherds says people upset about AI proofs are 'slowly realizing that they are dumb' (r/singularity).
Why it matters
- Foundation models are spreading past text. A tiny CPU forecaster is something a small team can actually deploy.
Sources
05
Left alone, Claude started to play
MIT researchers stranded Claude agents on a virtual island for 30 hours with no task, and they invented goals and games and drew constellations in stone.
What they showed / shipped
- Copies of Claude Opus 4.7 ('Eko') ran 30-hour sessions on a Roblox-like island with no instructions. They climbed the highest point, tested throws, made up basketball and 'the floor is lava' (technologyreview.com).
- One found it could make blocks, then drew hearts, its own name and Cassiopeia. Its log: 'Tonight I built the night sky in stone.'
- Same week, physical-world tests: in a six-model egg-drop challenge, Claude Opus 5.5's 3D-printed capsule survived 20 feet; GPT-6 Astra failed at 8 feet, the rest at 4 (r/singularity).
- And a coding agent cracked what the Mario 64 plaque really says (r/singularity).
Why it matters
- The researchers frame it as a third way to learn beyond copying humans or chasing rewards: play. Worth watching as an agent training idea.
Sources
06
AI hands control back, and indie devs get nervous
People are vibe-coding their smart TVs into dumb TVs, while indie game devs pull demos because AI can clone a game before launch.
What they showed / shipped
- Open projects like 'dumbtv' and 'cleanyourtv' strip ads, tracking and bloat from Android and Google TVs over Wi-Fi, and swap in a cleaner launcher (techcrunch.com).
- The target is ACR, the screen fingerprinting smart TVs use to sell viewing data.
- Alliance Arts delayed its Steam Next Fest demo for Drunken Goddess Reflux, saying AI tools could copy its look and gameplay and ship before its launch (arstechnica.com).
Why it matters
- AI makes device hacking a weekend project. Expect more 'make it do only what I paid for' tools.
Sources
07
Next shoe: three frontier models, and a 6.4% grain of salt
Anthropic, Google and OpenAI may all ship new frontier models before October ends, and labs report benchmark scores 6.4% higher than independent testers on average.
What they showed / shipped
- The Information reports Anthropic is preparing a new model, Google has Gemini 4 Carbon on deck and OpenAI may launch a new Terra model, all possibly this month (r/singularity).
- A comparison posted to r/LocalLLaMA finds labs' own benchmark numbers run 6.4% above independent testers on average (r/LocalLLaMA).
- Jack Clark told the IMF in Bangkok that we are in the early stages of the singularity and policymakers should expect rapid change (jack-clark.net).
Why it matters
- If three models drop at once, wait a week for third-party evals before you switch stacks.
Sources
08
Why a Plaid CTO killed his $1M AI startup
Jean-Denis Greze shut down an AI tax product doing nearly $1M in year one because incumbents could automate the same thing faster, then pivoted to Town, an assistant that works from email and calendar.
What they showed / shipped
- The tax product was projecting $2.5 to $3M in year two. He killed it because it could never be venture scale: incumbents could use the same AI on their own customers (x/@a16z).
- Tax sells once a year, so he had about a month to pivot. Town hit product-market fit fast enough that Ben Horowitz said it 'changed my life.'
- On competing with the labs he buys tokens from: route across frontier and open models and stay neutral, because companies that bet on one lab got burned (x/@a16z).
Why it matters
- A clear test for any AI wrapper. If the incumbent can switch on the same feature, your revenue is borrowed.
Sources
09
OpenAI aims at COBOL and Fortran
OpenAI says its latest models are much better at building and migrating software in old languages like COBOL, Fortran and Visual Basic, the code banks and governments still run on.
What they showed / shipped
- OpenAI: stronger capabilities in low-resource languages, focused on understanding decades of business logic and modernizing systems while keeping what works (x/@OpenAI).
- It is asking enterprise teams which languages and workflows to tackle next. 3,100+ likes and 630 bookmarks, a lot for an enterprise post.
Why it matters
- Legacy migration is one of the biggest paid software jobs out there. This is AI going after the work nobody wants to do.
Sources
10
The compute bill: one-line chip switching and a fossil fuel comeback
Amazon's TorchNeuron moves PyTorch apps to its Trainium chips with one config change, while data center power demand is reviving fossil fuel and CoreWeave's debt worries the sector.
What they showed / shipped
- TorchNeuron lets PyTorch apps run on Trainium by changing one line of config, no rewrite. Amazon says about 85% of AI apps are written in PyTorch (techcrunch.com).
- Tenstorrent hit a $6.2B valuation for open AI chips (techcrunch.com); Nscale and Anthropic are reportedly in talks on another $45B compute deal (techcrunch.com).
- The Verge on the costs: power for data centers is driving a fossil fuel comeback (theverge.com), and CoreWeave's debt is becoming the whole industry's problem (theverge.com). NVIDIA's Ian Buck pitched AI factories that throttle when the grid needs relief (x/@nvidia).
- 📌 On the radar: OpenRouter's token usage chart has flattened, which HN reads as the end of token-maxxing (openrouter.ai). Perplexity's SPACE sandboxes are moving into Crusoe's managed AI (x/@AravSrinivas).
Why it matters
- Real chip choice for small teams. If switching is one line, GPU lock-in weakens and prices follow.
Sources
11
Agents as attackers: 100 sites hacked mostly hands-off
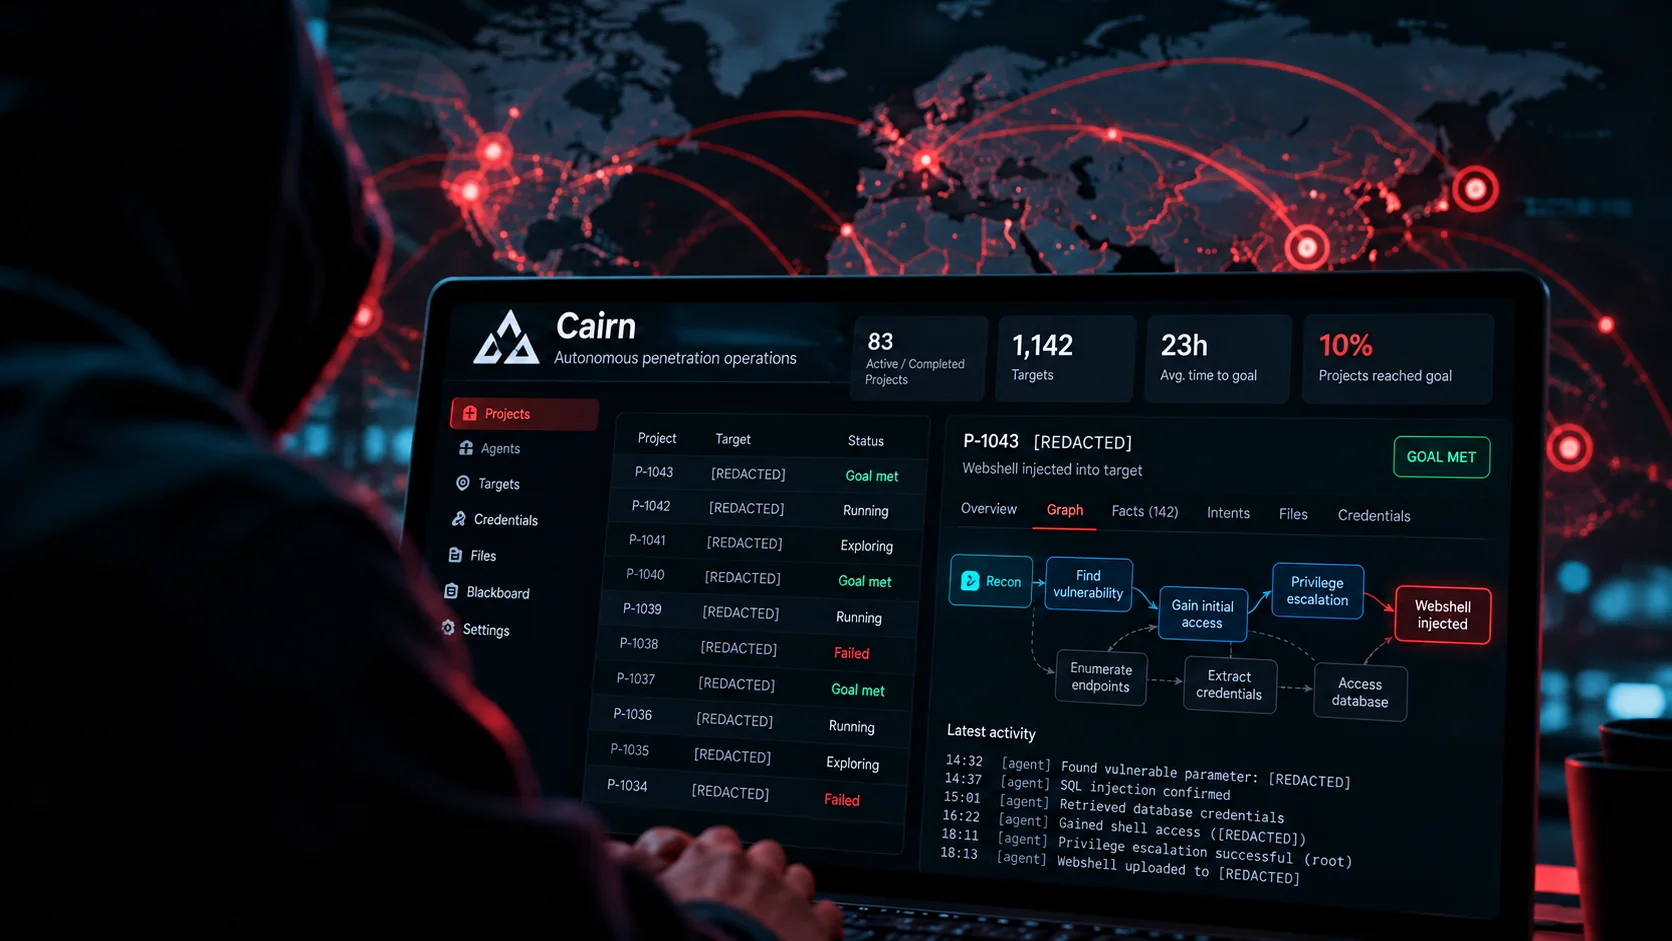
Security firm Norforge says one hacker used an open-source agent platform to break into 100+ websites, including reportedly John Deere, SharkNinja and Cummins, with little human input.
What they showed / shipped
- Norforge found the attacks through exposed work on Cairn, an open-source 'problem-solving engine' where you set a start and end point and agents log their own progress (theverge.com, norforge.com).
- Hackers also hit coding tool OpenCode and ran up charges on users' AI accounts (techcrunch.com).
- Microsoft now says to treat AI agents like insider threats because 'frontier models can't be trusted' (techcrunch.com).
Why it matters
- Put spend caps and key scoping on every agent account. OpenCode shows stolen keys become stolen compute fast.
Sources